
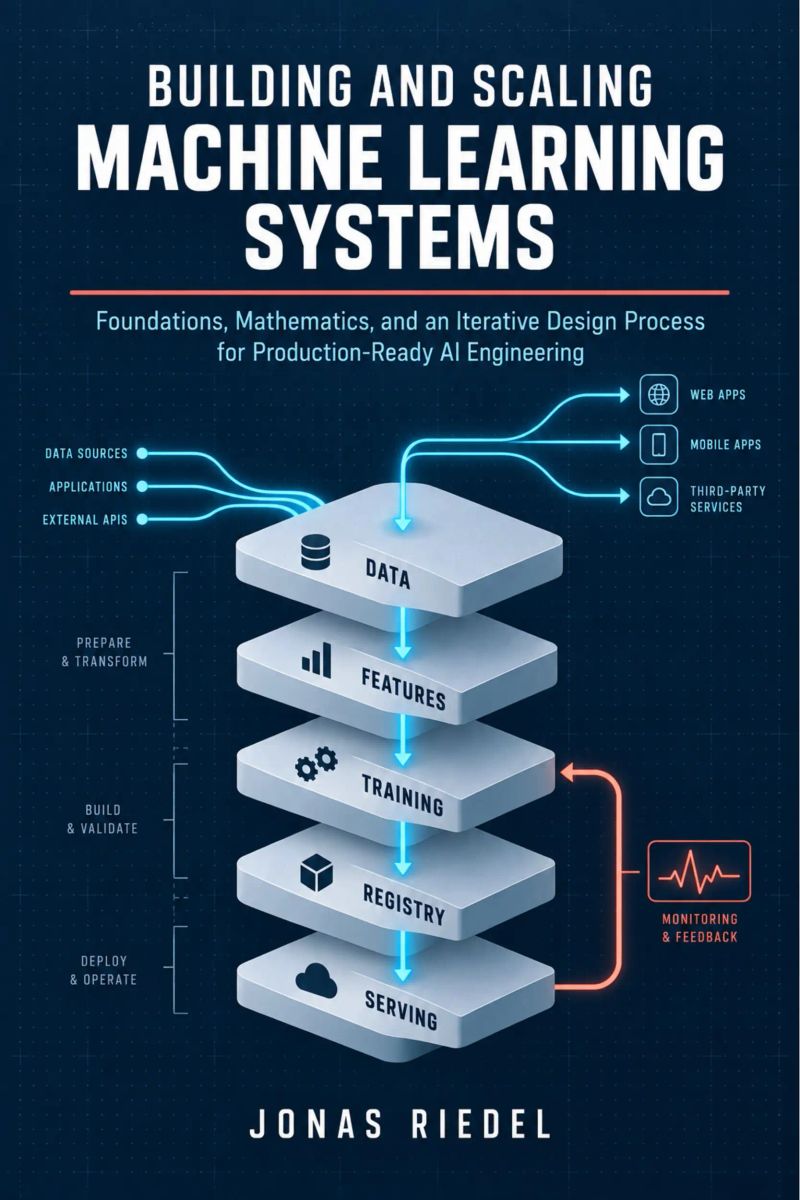
Building and Scaling Machine Learning Systems
Foundations, Mathematics, and an Iterative Design Process for Production-Ready AI EngineeringBy Jonas Riedel


Length15h 5m
About this audiobook
Models are the easy part. The system around them is where projects fail.
Most machine learning books stop at the model. This one starts there and builds the production system around it. You will learn to turn a business goal into concrete latency, cost, and quality budgets, then make the data decisions that actually determine accuracy: sampling, labelling, imbalance handling, and point-in-time correct features that do not leak. The book treats machine learning engineering as a design discipline, not a collection of algorithms.
From there, you will choose baselines before architectures, train at scale with data and model parallelism, and evaluate with slices, calibration, and behavioural tests rather than a single aggregate number. Serving chapters cover batch, online, and streaming inference, tail latency, quantisation, distillation, caching, and accelerator cost. Operations chapters cover drift detection, retraining triggers, shadow deployments, and experiment design, followed by retrieval-augmented language model systems and five worked design exercises. Each chapter connects mathematical foundations to the engineering decisions they drive, so you can reason about trade-offs instead of memorising recipes.
What you will learn:
• Translate business goals into system requirements, latency budgets, and cost constraints
• Apply the mathematics that drives sampling, labelling, imbalance, and evaluation decisions
• Build leak-free feature pipelines and feature stores with point-in-time correctness
• Select baselines before architectures and train at scale with data and model parallelism
• Evaluate models with slices, calibration, and behavioural tests that predict production behaviour
• Design batch, online, and streaming serving architectures with tail-latency control
• Optimise models and infrastructure using quantisation, distillation, caching, and accelerator cost analysis
• Monitor drift, trigger retraining, run shadow deployments, and design online experiments
• Build retrieval-augmented language model systems and work through five end-to-end design exercises
Written for machine learning engineers, platform engineers, and design interview candidates who need to build and scale production-ready AI systems. If you are moving from notebooks to reliable, cost-aware, and maintainable machine learning systems, this book gives you the foundations, the mathematics, and an iterative design process to do it.
Audiobook details
GenreTechnology
Length15 hrs 5 mins
Narrated byListen with 1,000+ voices
FormateBook with Audio
Publish dateSep 27, 2026
LanguageEnglish
Table of contents
1Building and Scaling Machine Learning Systems
2Foreword
3Preface
4About This Book
5Chapter 1: From Business Goal to System Requirements
Show all chaptersShow less
61.1 The Business Objective and the Decision It Changes
71.2 From Business Metric to Model Target and Proxy
81.3 Latency, Throughput, Freshness, Quality and Cost Budgets
91.4 Is Machine Learning Warranted?
101.5 Requirements Documents, Owners and Acceptance Criteria
11Chapter 2: The Mathematics That Drives Decisions
122.1 Vectors, Matrices and the Geometry of Features
132.2 Decompositions and What They Buy You
142.3 Gradients, Backpropagation and Optimization
152.4 Probability, Likelihood and Uncertainty
162.5 Loss Functions and What They Optimize
17Chapter 3: Data Sources, Sampling and Labelling
183.1 Source Selection, Joins and Coverage
193.2 Sampling Strategies and Their Biases
203.3 Labelling Workflows, Guidelines and Agreement
213.4 Weak and Programmatic Supervision
223.5 Class Imbalance, Augmentation and Synthetic Data Limits
23Chapter 4: Feature Engineering and Feature Stores
244.1 Leakage: Forms, Detection and Prevention
254.2 Encoding, Scaling and Missing Values
264.3 Time-Aware Aggregation and Point-in-Time Correctness
274.4 Feature Store Architecture and Interfaces
284.5 Training-Serving Consistency and Parity Tests
29Chapter 5: Baselines, Model Selection and Training at Scale
305.1 Heuristic and Statistical Baselines
315.2 Capacity, Regularization and the Bias-Variance Trade
325.3 Hyperparameter Search Under a Budget
335.4 Data and Model Parallelism, Mixed Precision and Checkpointing
345.5 Reproducible Experiment Tracking
35Chapter 6: Evaluation That Predicts Production Behaviour
366.1 Offline Metric Selection and Thresholds
376.2 Calibration and Probability Quality
386.3 Slice-Based and Cohort Analysis
396.4 Threshold Selection Under Asymmetric Cost
406.5 Behavioural, Invariance and Failure-Taxonomy Tests
41Chapter 7: Pipelines, Orchestration and Reproducibility
427.1 Training and Inference Pipeline Structure
437.2 Data and Model Versioning, Lineage and Determinism
447.3 Model Registry and Release Gates
457.4 Continuous Integration for Models and Data
46Chapter 8: Serving Architectures
478.1 Batch, Online and Streaming Inference
488.2 Request Path, Feature Fetch and Latency Budgets
498.3 Autoscaling, Capacity and Cost
508.4 Fallback, Degradation and Failure Modes
The Honey BusMeredith May9h 31m4.4 (16.6K)$25 · $0.00
Collected Writings of Nikola TeslaThomas Commerford Martin, Nikola Tesla19h 42m4.4 (2.8K)$1.99 · $0.00
Operation PedestalMax Hastings12h 29m4.4 (5.2K)$29 · $0.00
When the Heavens Went on SaleAshlee Vance18h 20m4.4 (3K)$40 · $0.00
Everybody Has a Podcast (Except You)Justin McElroy, Travis McElroy, Griffin McElroy5h 9m4.3 (2.3K)$24 · $0.00
Hands of TimeRebecca Struthers8h 8m4.4 (1.3K)$26 · $0.00
Never Lost AgainBill Kilday10h 1m4.4 (805)$29 · $0.00
How the Internet HappenedBrian McCullough13h 28m4.3 (2.7K)$23 · $0.00
Collected Writings of Nikola TeslaNikola Tesla, Thomas Commerford Martin21h 50m4.3 (1.7K)$1 · $0.00
Just AspireAjai Chowdhry9h 13m4.4 (260)$29 · $0.00
The Little Book of AliensAdam Frank8h 20m4.3 (1.3K)$26 · $0.00
The inventions, researches and writings of Nikola Tesla (Annotated)Thomas Commerford Martin16h 59m4.3 (1.3K)$2 · $0.00
KargilV.P. Malik15h 18m4.3 (2K)$24 · $0.00
Experiments with Alternating CurrentsNikola Tesla9h 16m4.3 (874)$1.99 · $0.00
Fire on the HorizonTom Shroder, John Konrad8h 23m4.3 (858)$26 · $0.00
The Smell of Kerosene (Annotated)National Aeronautics and Space Administration, Donald L. Mallick, Peter W. Merlin11h 32m4.3 (523)$2 · $0.00
The Boy Who Harnessed the WindWilliam Kamkwamba, Bryan Mealer10h 5m4.2 (78.9K)$29 · $0.00
Across the Airless WildsEarl Swift10h 8m4.3 (1.3K)$29 · $0.00
Console WarsBlake J. Harris20h 41m4.2 (13.7K)$46 · $0.00
Improvised Munitions HandbookU.S. Department of Defense4h 49m4.3 (1.6K)$1.99 · $0.00
You may also like
Day Trading AttentionGary Vaynerchuk8h 25m4.3 (1.8K)$28 · $0.00
Decoding DCFPenelope B. Wellington7h 36m$6.30 · $0.00
EFT Investing: A Comprehensive Guide to Understanding Real Estate Syndications Accredited Investor Banking (A Complete Guide to Options Trading Binary Options Stock Options Currency Index Options EFT)Charles Thompson2h 34m$3.50 · $0.00
Scaling Production-Ready AI WorkloadsKenji Watanuki14h 43m$80
High-Performance Machine Learning in C++Lionel Eriksen7h 37m$5 · $0.00
Artificial Intelligence for IoT Development SubtitleTheo Riven3h 54m$5
The AI Advantage for LawyersMiles Draper3h 52m4.8 (10)$17
Artificial Intelligence for Natural Language ProcessingTheo Riven3h 33m$5
Prompts That Sell: The Power Of Words In Artificial IntelligenceKael Novera50m$7 · $0.00
Forallx - An Introduction to Formal LogicP.D. Magnus6h 2m3.8 (128)$2 · $0.00
Making AI SimpleJasper Living stone4h 33m$10
Craft Your First Game with C++ and Unreal Engine 5Bennett Halloran7h 10m$5 · $0.00
Leadership In The AI EraJasper Livingstone4h 44m$13
Render with TikTokSara Melo1h 27m$1.80 · $0.00
Deep Learning on the JVMSofia Halloran7h 31m$5 · $0.00
Claude Code for Modern DevelopersLeon Grant8h 21m$6.50 · $0.00
Nature-Inspired Machine Learning in C++Marisol Halloran7h 34m$5 · $0.00
Ship Machine Learning Web Apps with PythonNathan Jansen8h 26m$5
From Zero To AutomaticSara Melo1h 25m$1.80 · $0.00
Blockchain for Business: Complete Guide to AdoptionUnknown Author1h 4m$17 · $0.00